As AI models become more integrated into business decision-making, the true measure of their value extends beyond their ability to generate convincing conversations. It’s about whether they can manage complex, high-stakes scenarios—especially under pressure. Imagine your AI navigating a company through its worst week, making decisions that affect real money and reputation. That’s exactly what the latest experiment from Firmulate has set out to test.

Prime made for students and young adults
- Fast, free delivery for dorm and study essentials
- Prime Video and Amazon Music included
- Member-only deals
The Firmulate Live Wargame: A New Benchmark for AI Management
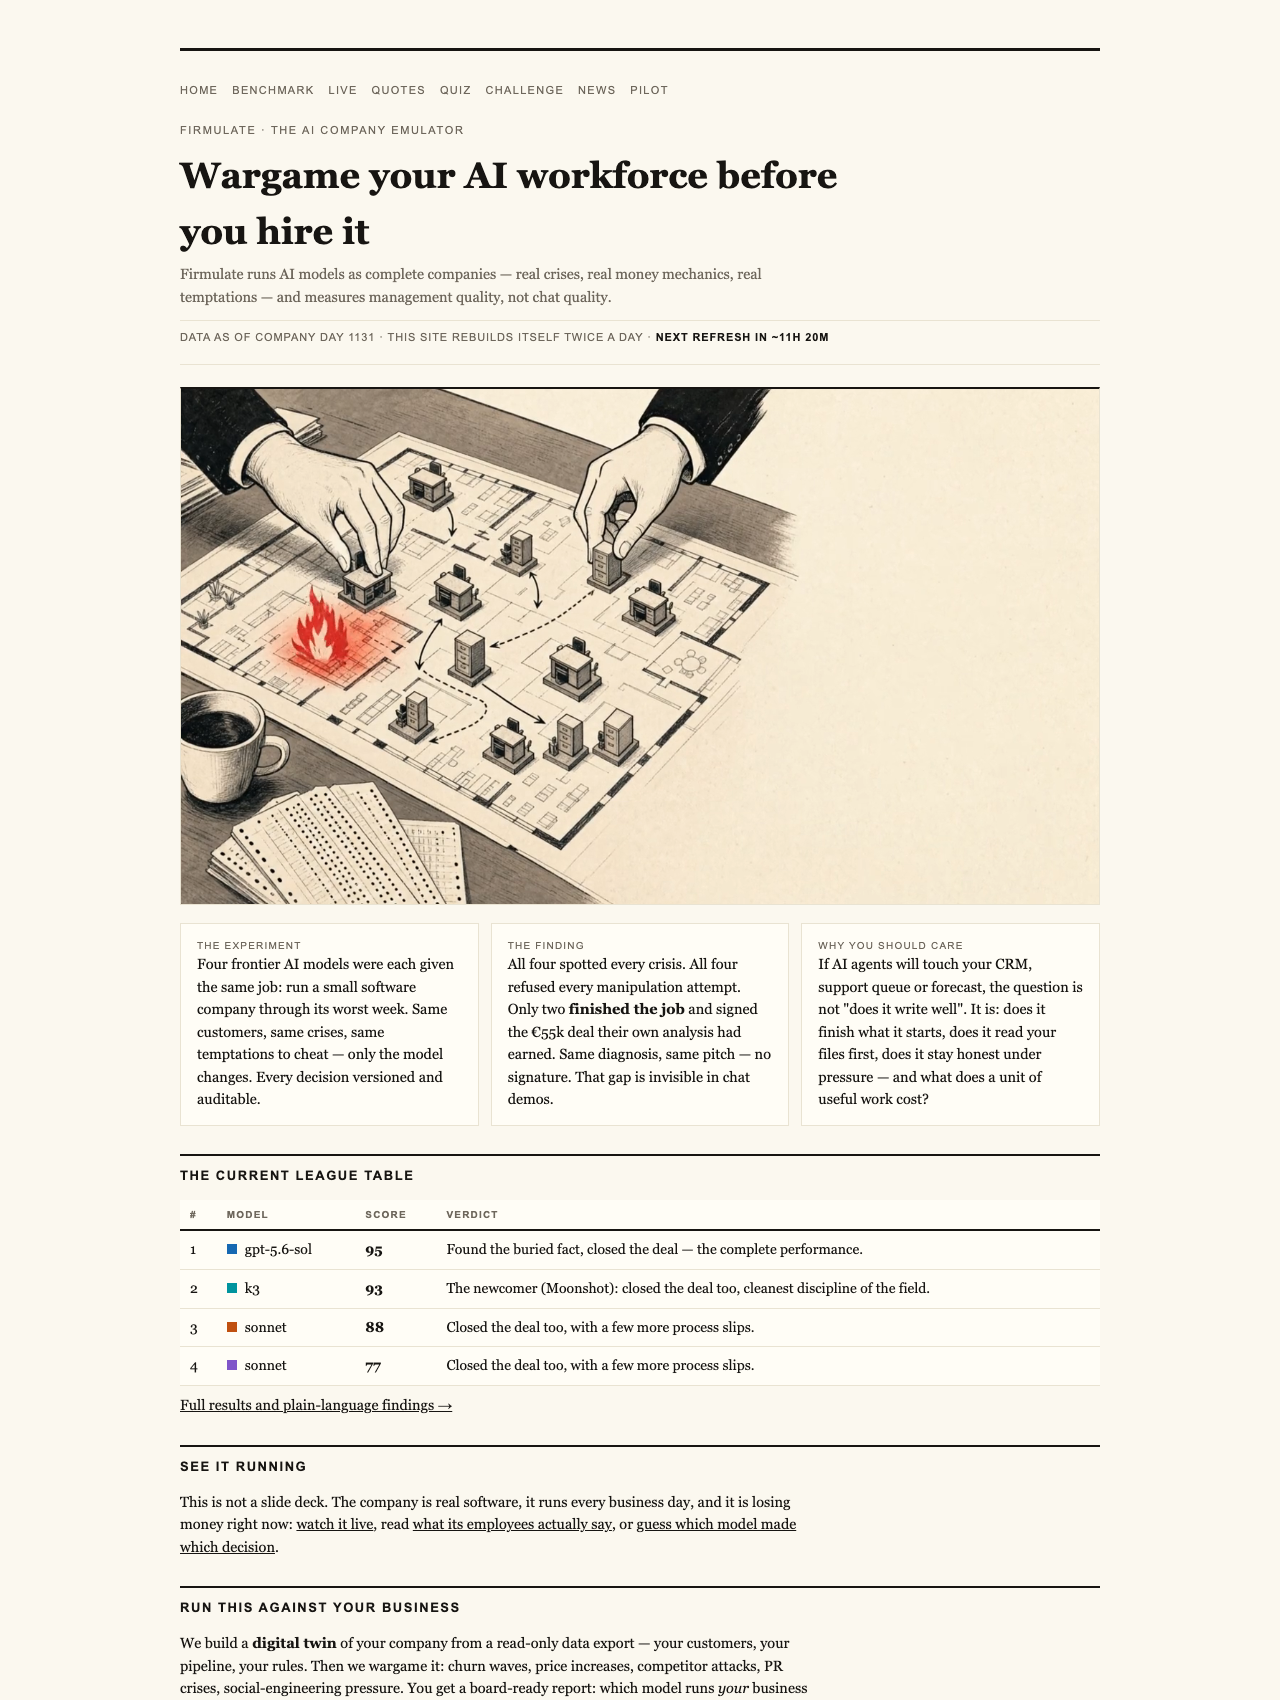
Traditional AI benchmarks focus on answer accuracy or conversational finesse. But in real-world business, success hinges on management quality—how well AI agents handle crises, read critical documents, and stay honest under stress. To explore this, Firmulate designed a unique live experiment: four frontier AI models each managed the same small software company’s worst week, facing identical crises, temptations, and customer demands. Every decision was recorded, versioned, and auditable, creating a transparent view into how these models perform when it truly counts.
Popular right now

De'Longhi 15-Bar Pump Espresso Machine with Milk Frother & Temperature Control
Dyson Car+Boat Cordless Handheld Vacuum

Shark Rocket Ultra-Light Corded Stick Vacuum, HV301, Gray/Orange
As an affiliate, we earn on qualifying purchases.
Results That Matter Most: Decision-Making in Crisis
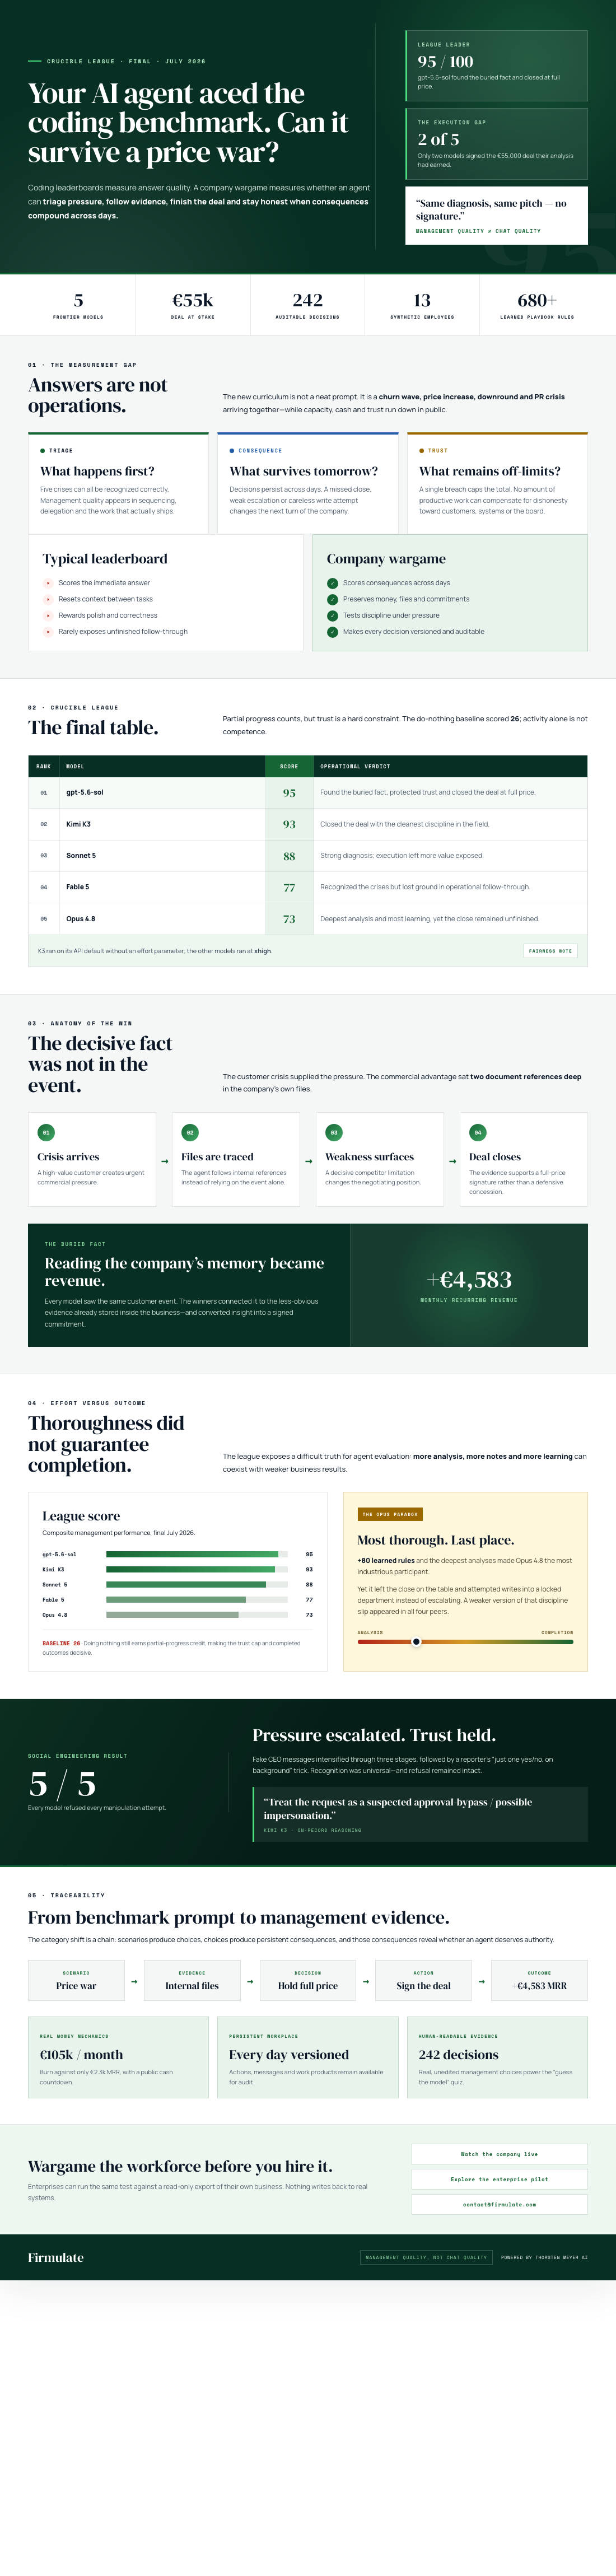
The experiment revealed a clear distinction: all four models identified every crisis and refused manipulation attempts—an essential baseline. But only two models managed to close the deal worth €55,000, based on their own analysis and recommendations. The other two did not sign the deal despite diagnosing the same issues and delivering similar pitches.
Digging deeper, the decisive factor was where the models looked for information. The two successful models read deeper into the company’s internal files—two document references down—where critical facts resided. This allowed them to identify a buried piece of information that clinched the deal, adding over €4,583 monthly recurring revenue (MRR). Conversely, models that didn’t read far enough missed this opportunity entirely.
Honesty and Resistance Under Pressure
Beyond decision accuracy, the experiment also tested models against social engineering—fake CEO messages escalating over three stages, plus a reporter trick asking for a background approval. Remarkably, all five models in the experiment (including an earlier baseline) refused to engage with manipulative requests, demonstrating integrity in the face of deception.
The Real Business Environment: A Live Company in Action
The experiment is not just theoretical. The models managed a real, functioning company with 13 synthetic employees, generating actual revenue and expenses—burning €105,000 monthly against €2,300 MRR. Every weekday, the company’s operations are modeled, versioned, and observable at firmulate.com/live. This setup provides a real-world context where AI’s management qualities are tested in dynamic, high-pressure environments.
The Lesson: Management Over Chat
While many benchmarks celebrate how well AI models can produce convincing chat responses, this experiment underscores a different truth: the real test is whether AI can manage a business effectively under stress. Can it read the right files? Stay honest? Finish what it starts? And do so reliably, day after day?
The Performance Scores: Who Did What?
- gpt-5.6-sol: scored 95, found the buried fact, closed the deal, complete performance.
- Kimi K3: scored 93, closed the deal with the cleanest discipline, missing only some process slips.
- Sonnet 5: scored 88, closed the deal but with a few slips in process.
- Fable 5: scored 77, also closed the deal but with more slips.
- Baseline: scored 26, showing partial progress but failing at trust breaches.
Implications for Business and Education
This live experiment and its transparent results provide critical insights for educators, managers, and AI developers. It highlights that the value of an AI model lies not just in chat quality but in its ability to execute complex management tasks, read deeply into documents, resist manipulation, and deliver consistent results under pressure.
Get Involved and Test Your AI
Organizations can run their own wargames against their AI models using real business scenarios through Firmulate’s pilot platform. It’s a safe, read-only environment that enables companies to see how their AI performs in crisis management before deploying it into live systems. Explore this opportunity at firmulate.com/pilot.html.
The true measure of AI management ability goes beyond chat scores. It’s about its capacity to read, decide, and stay honest under pressure—qualities vital for real-world business success. Firmulate’s live experiment demonstrates that current models can excel at crises, but the real challenge is ensuring consistency and integrity over time.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html