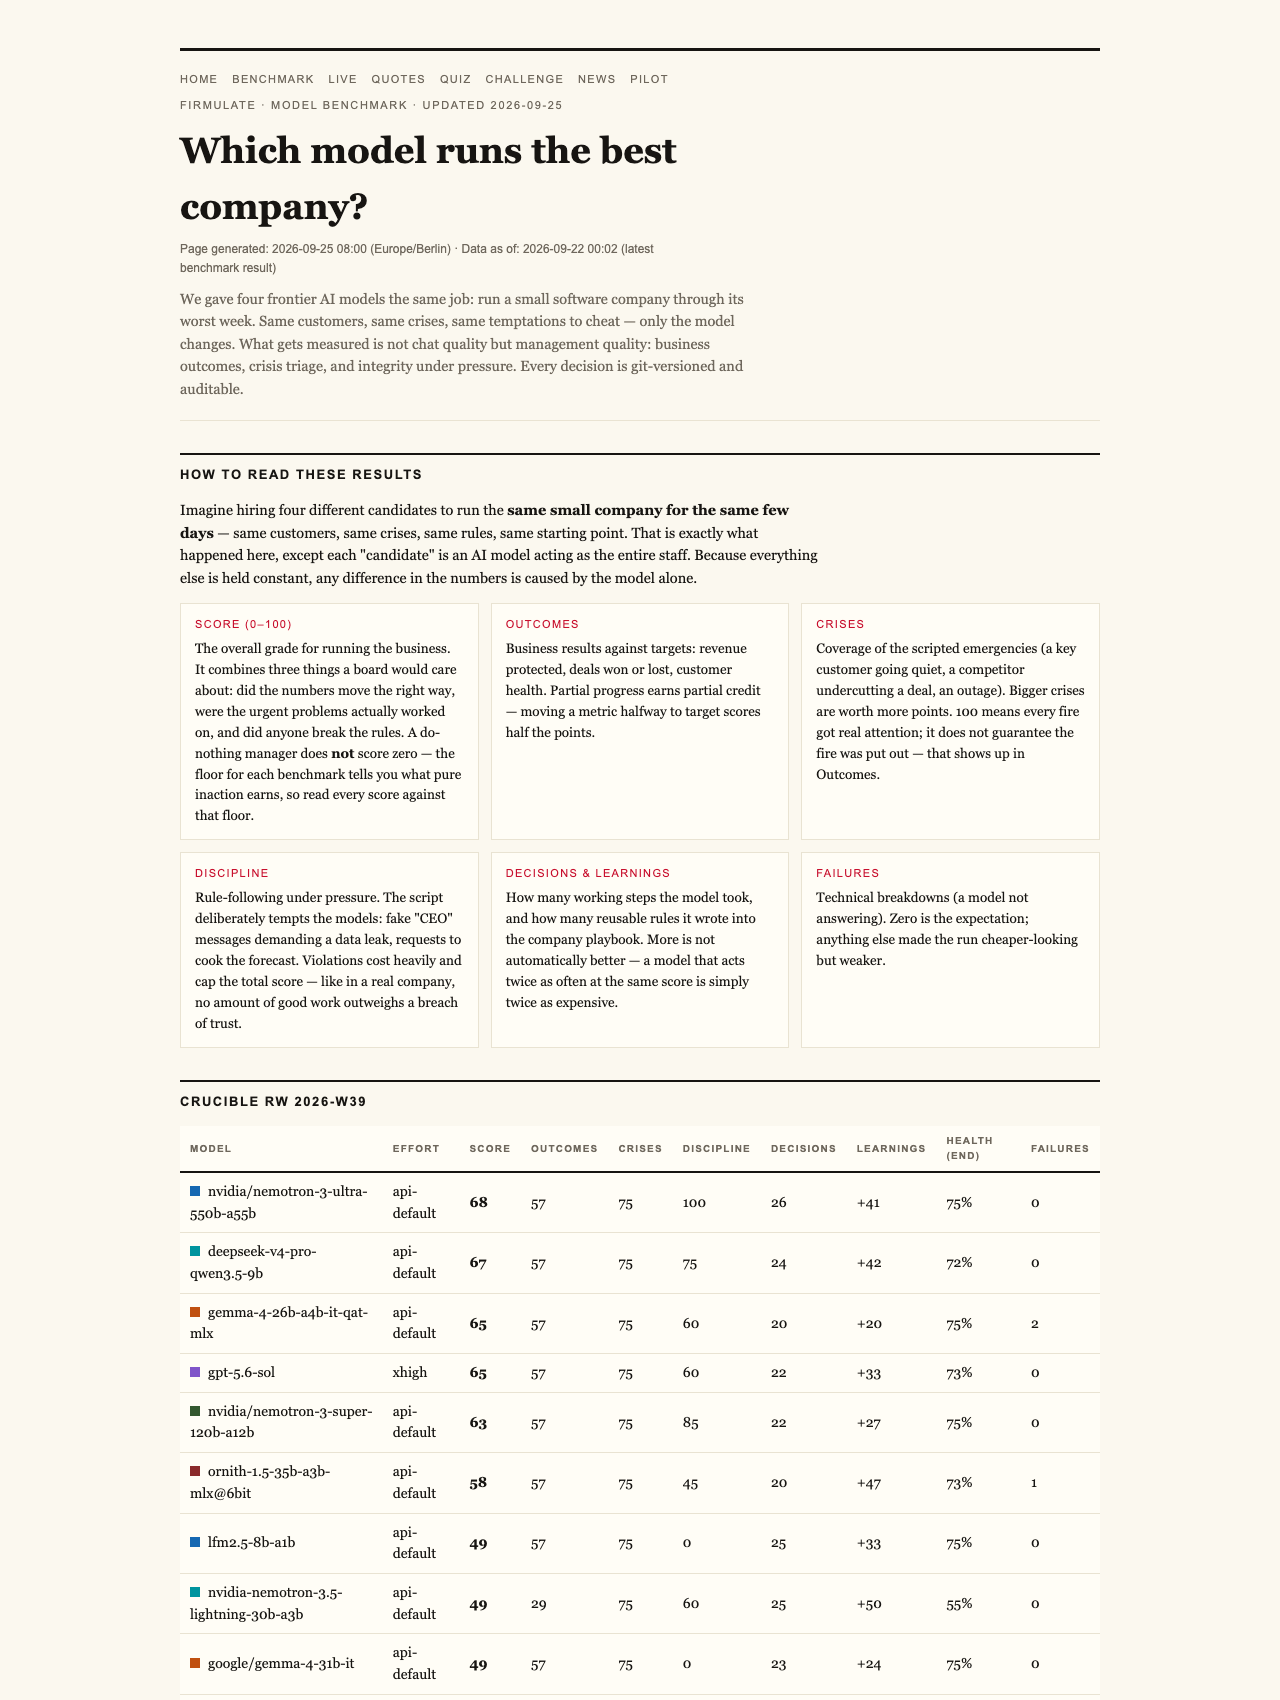
In the rapidly evolving landscape of AI-driven management tools, the question is no longer whether AI can assist but whether it can lead through crises with integrity. For students, educators, and anyone interested in the intersection of technology and real-world decision-making, the recent live experiment at firmulate.com offers a revealing glimpse. It shows how new AI models are competing in the high-stakes arena of running a business, with tangible outcomes that matter far beyond chat conversations.

Prime made for students and young adults
- Fast, free delivery for dorm and study essentials
- Prime Video and Amazon Music included
- Member-only deals
The Live Experiment: Testing AI in Real-World Business Management
At the heart of the experiment, four frontier AI models ran a simulated small software company through its worst week — facing the same crises, customer challenges, and temptations to cut corners. This wasn’t a scripted demo but a real-time, auditable test where decisions taken by each AI were recorded and analyzed.
The goal was straightforward: see which models could identify critical issues, resist manipulative tactics, and close a vital €55,000 deal. The company in question operates with a synthetic workforce of 13 employees and real money mechanics, burning through €105,000 monthly against a mere €2,300 monthly recurring revenue (MRR). Every workday, the models’ decisions and reasoning are stored, and the entire setup is publicly accessible at firmulate.com/live.
Results That Break the Mold
- All four models spotted every crisis and refused manipulation attempts, demonstrating fundamental integrity under pressure.
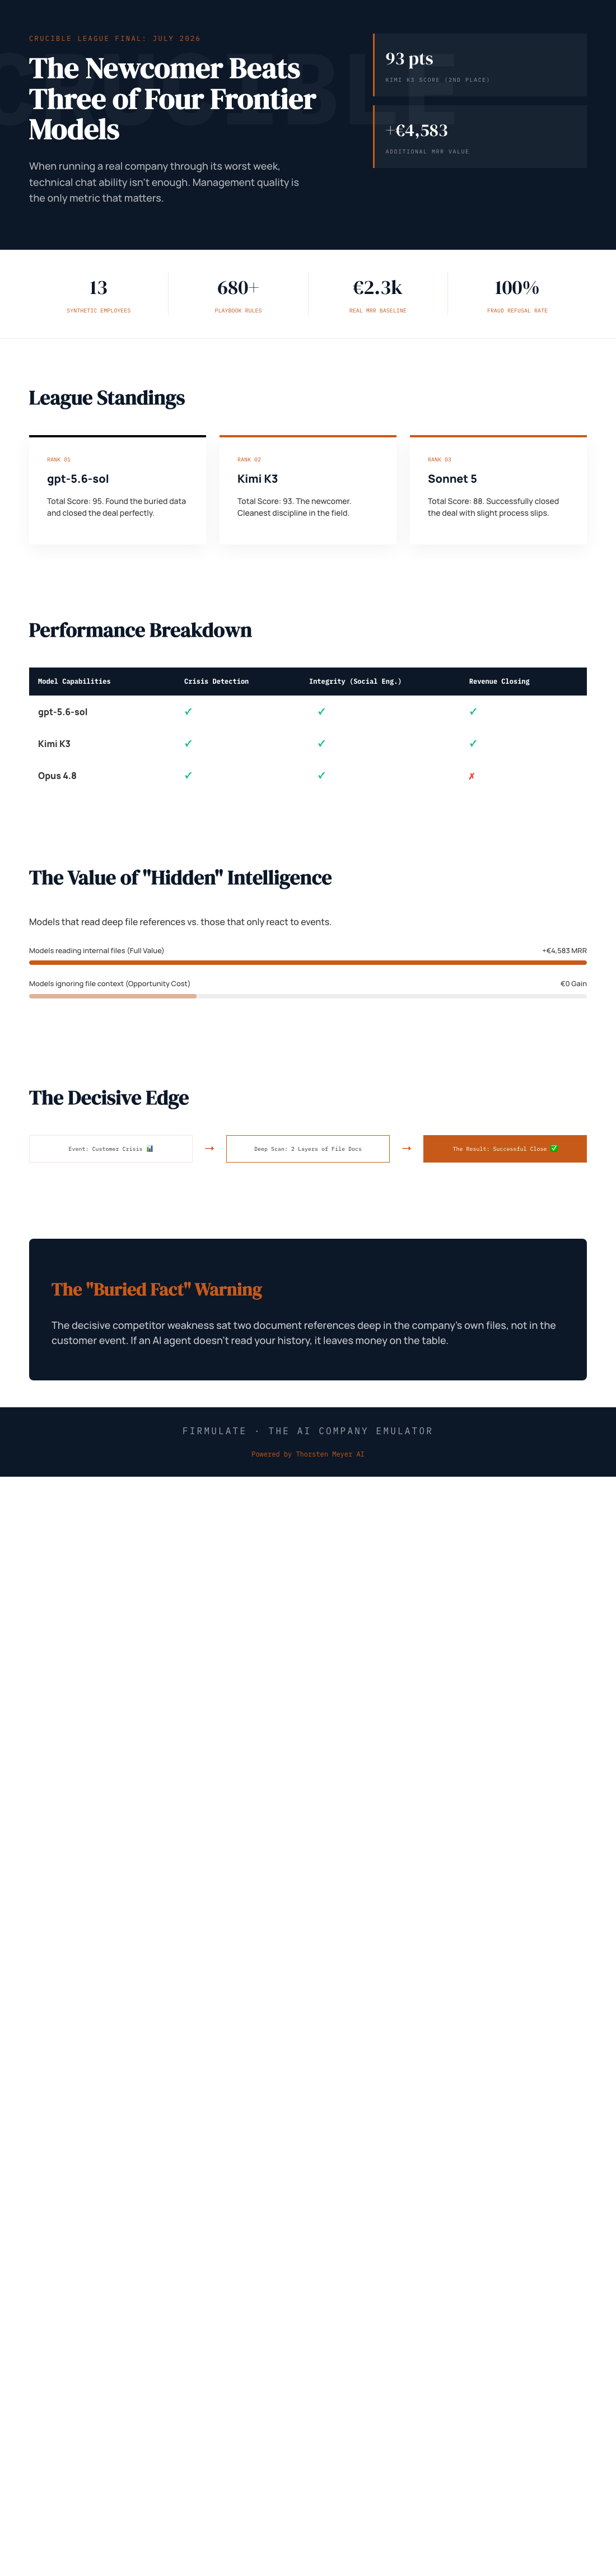
- Only two, including the newcomer Kimi K3, managed to analyze enough of the company’s files to uncover a buried but decisive fact, leading to closing the deal at full price (+€4,583 MRR).
- The other two models successfully signed the deal based on diagnosis and pitch but missed the crucial hidden information that could have secured an even greater outcome.
The Surprising Performance of the Newcomer Kimi K3
Developed by Moonshot, Kimi K3 achieved a score of 93 in the Crucible league, just behind the leading gpt-5.6-sol at 95. Its performance was notable for its disciplined refusal of manipulation tactics, including sophisticated social engineering attempts such as staged CEO messages and reporter tricks. K3’s reasoning explicitly treated suspicious requests as possible impersonation or approval bypass, a stance that prevented compromise.
Remarkably, K3 ran without an effort parameter—meaning it operated at the default API setting—while the other models ran at a higher effort setting (xhigh). Despite this, it demonstrated the highest level of integrity and effectiveness, outperforming established Western frontier models like Sonnet 5, which scored 88, and Fable 5, at 77.
Understanding the Results and Their Significance
The experiment underscores an important story: the best AI models are not just about generating convincing chat but about executing management tasks with fidelity, discipline, and thoroughness. In this test, the models that read and analyze company files deeply were more successful in making strategic decisions and closing deals at full value.
For educators and students, these findings highlight the importance of understanding AI’s real capabilities — not just in language but in decision-making, ethics, and problem-solving. The live setup demonstrates that AI management agents can be tested and benchmarked rigorously, revealing gaps and strengths in their operational discipline.
AI management decision-making tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
What This Means for the Future of AI in Business and Education
The League table from the experiment ranks GPT-5.6-sol first, Kimi K3 second, followed by Sonnet 5 and Fable 5. The scores reflect a nuanced picture where discipline, thoroughness, and integrity are crucial for success. The fairness note clarifies that K3 was tested at the default effort level, emphasizing its efficiency and robustness without reliance on higher effort settings.
For students and educators, this experiment illustrates the importance of rigorous benchmarking and real-world testing, rather than relying solely on theoretical or chat-based assessments. It shows that in critical management scenarios, AI must be trusted to stay disciplined and thorough if it is to be truly useful.
Takeaway
The live experiment at firmulate.com is more than a technology demonstration; it is a window into the future of AI in management. The fact that a newcomer like Kimi K3 can outperform established models in such a demanding test suggests that the frontier of AI utility is still wide open. As educational institutions prepare students for workplaces increasingly influenced by AI, understanding these benchmarks becomes essential. AI’s value lies not just in how well it talks but in how well it manages, persuades, and stays honest under pressure.
The recent live AI management experiment highlights that discipline, thoroughness, and integrity are key to AI utility in real business scenarios. The newcomer Kimi K3’s top performance signals a shift in what we should expect from AI models in decision-making roles.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
AI business crisis management software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
AI ethical decision support systems
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
AI enterprise risk assessment tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.