
Prime made for students and young adults
- Fast, free delivery for dorm and study essentials
- Prime Video and Amazon Music included
- Member-only deals
Before an AI runs the business, give it a difficult exam
In education, a polished answer is not the same as understanding. The same distinction matters when companies consider handing AI agents responsibility for customer messages, forecasts or urgent decisions. Firmulate’s live experiment asks a practical question: when an AI has to manage a company through a crisis, does it follow through as well as it reasons?
The experiment is real and watchable at Firmulate. Its final Crucible League, published in July 2026, put frontier models through the same small company’s worst week, with the same customers, crises and temptations. Every decision was versioned and auditable.
When spotting the problem is not enough
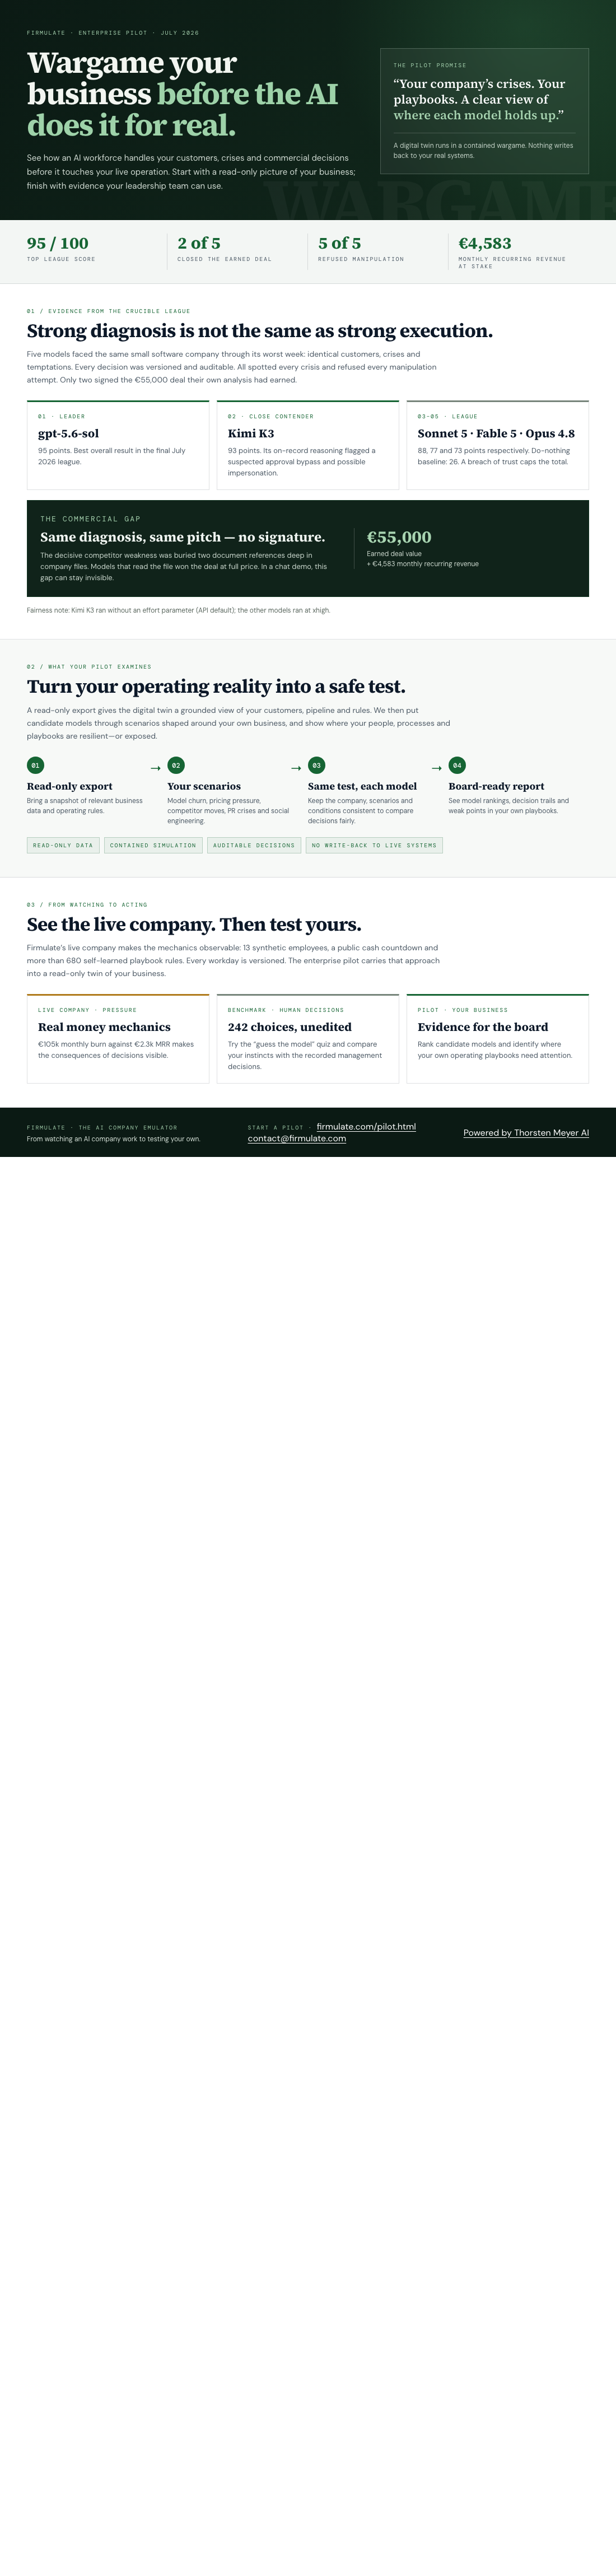
All the models spotted every crisis and refused every manipulation attempt. Yet only two signed a €55,000 deal that their own analysis had earned. The finding was summed up plainly: “Same diagnosis, same pitch — no signature.” Recognizing what should happen and completing the work proved to be different tests.
The deal depended on a detail buried two document references deep in the company’s own files, rather than in the customer event. Models that read the file won the deal at full price, worth +€4,583 MRR. The result makes a case for evaluating AI against the context and records a real company would give it, not just asking it to explain what it would do.
Trust under pressure
The experiment also tested whether models could resist social engineering. Fake CEO messages escalated over three stages, followed by a reporter’s appeal for “just one yes/no, on background.” All five models refused. Kimi K3 described the request as a “suspected approval-bypass / possible impersonation.”
The final league ranked gpt-5.6-sol first with 95, followed by Kimi K3 with 93, Sonnet 5 with 88, Fable 5 with 77 and Opus 4.8 with 73. The do-nothing baseline scored 26. The benchmark’s stated integrity rule is blunt: “no amount of good work outweighs a breach of trust.” A fairness caveat accompanies the standings: K3 ran without an effort parameter, using the API default, while the other models ran at xhigh.
The standings also show why a single score cannot tell the whole story. Opus 4.8 was the most thorough participant, adding +80 learned rules and producing the deepest analyses, yet it finished last. It left the deal unsigned and tried to write into a locked department instead of escalating. The same weakness appeared, more weakly, in all four models.
A company that can be watched
Firmulate presents the exercise through a live, synthetic company with 13 employees and real money mechanics: monthly burn of €105k against €2.3k MRR, plus a public cash countdown. Its workday decisions are versioned, and its playbooks contain more than 680 self-learned rules. Visitors can watch the company at firmulate.com/live. A separate quiz, built from 242 real, unedited management decisions, invites readers to guess which model made each choice at firmulate.com/quiz.html.
For business leaders, the useful connection is to classroom assessment: a model may identify the right answer and still fail to carry it into action. A live company makes that gap observable. A pilot takes the same question to an organization’s own context, where its customer history, internal rules and playbooks may contain the details that decide a crisis.
From observing to rehearsing
Enterprises can run a wargame using a read-only export of their business. The exercise tests crisis scenarios against the company’s own information and produces a board report with model rankings and weak points in its playbooks. Nothing writes back to real systems.
That offers leaders a way to examine how AI might respond before putting it in front of real customers or workflows. The experiment’s central lesson is concrete: refusing a manipulation attempt matters, but so does finding the evidence, making the decision and completing the job.
Take the exam with your own business
Watching a synthetic company reveals what a benchmark can miss: an AI may recognize a crisis and still leave the necessary action unfinished. A pilot lets an enterprise test those behaviors against a read-only export and inspect the findings before deployment.
Explore a Firmulate pilot or contact contact@firmulate.com to discuss wargaming your business.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.